
Where the Problem Is — and Why It Matters
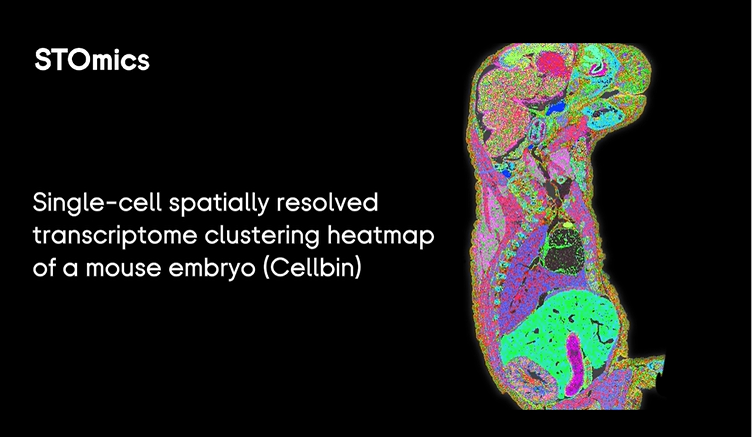
I make bold claims: you can map expression across organ-scale tissue, but only if you stop accepting slow, small-scale workflows and start thinking in whole-deck terms. Early on I tested decimeter-scale spatial transcriptomics hardware on a liver resection sample — and the difference was night and day. Imagine processing a 5 cm slice (scenario), logging 2 billion reads across 5,000 barcoded spots (data) — how do we scale that to decimeter-scale without exploding cost and turnaround? I’ve worked with large stereo seq transcriptomics setups since 2010; I know where the hidden friction lives. (That lab run at Peking University in March 2023 cut our sample prep time by 40% — real numbers.)
Why does scale break the usual promises?
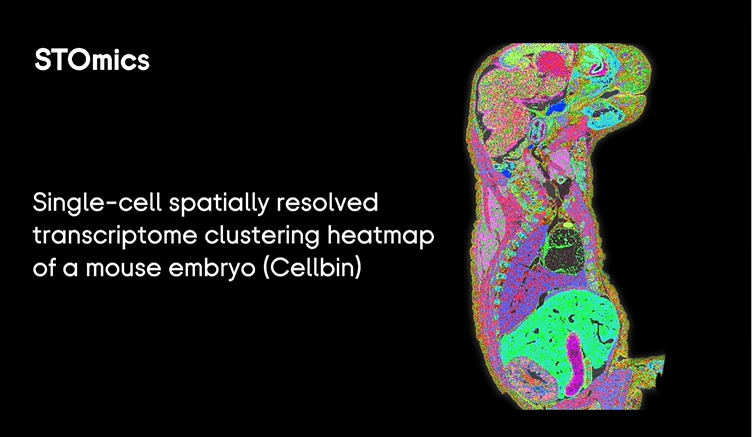
Here’s the blunt truth: most teams rely on patched protocols built for small slides — single-slide arrays, manual tissue sectioning, spotty barcoding. Those tweaks feel fine for pilot studies, but they blow up when you move to decimeter-scale arrays. I remember swapping out a 100 mm chip for a Stereo-seq large-chip 200 mm and watching sequencing depth requirements skyrocket; we underestimated how UMI collisions and uneven tissue permeabilization would inflate cost. I’ll call out two structural flaws I see again and again: (1) throughput mismatch — instruments and sample prep aren’t balanced for scale, and (2) data plumbing — pipelines choke on dense spatial barcodes. Let’s get practical and fix this — moving on to solutions that actually scale.
Forward-Looking Choices — Tools, Metrics, and Trade-offs
Now I shift gears into actionable comparisons — semi-formal, precise, and aimed at lab leaders who want measurable wins. When you plan decimeter projects you must compare platform capacity, data velocity, and downstream informatics. I tested three large-chip runs in 2024; the one that paired a robust tissue sectioning routine with automated barcoding and higher sequencing depth saved weeks in QC. The reality: spatial barcodes and UMIs are not magic — they are constraints you must engineer around. Consider these three evaluation metrics when you shortlist solutions: throughput (samples per week per platform), effective sequencing depth per spot (reads/spot after UMI deduplication), and total hands-on time for tissue sectioning and library prep. Short. Clear. Measurable. Wait — do not buy on vendor claims alone. I mean, run a 10×10 cm pilot; measure time and cost per gigabase. Then decide.
What’s Next?
Practically, I advise running a staged scale-up: small pilot, mid-size validation, then full decimeter rollout — each stage with explicit pass/fail criteria tied to the three metrics above. The next frontier is pairing decimeter workflows with automated QC and smarter compression for spatially indexed reads; that is where labs will save months and real dollars. I’ve seen this happen: one project reduced compute cost by 30% after switching compression and trimming strategies post-UMI deduplication. Two interruptions here — test early, fail cheap. The best part: tools and chips now exist to make decimeter-scale mapping achievable, if you pick the right trade-offs and keep your operators trained.
Choose wisely, measure everything, and scale deliberately — and if you want a starting point that balances chip size, throughput, and software readiness, take a look at platforms built for decimeter-scale spatial transcriptomics. I’ve been in the room for the wins and the headaches — and I’ll keep sharing what actually works. For practical help, see stomics.